Frequently Asked Questions

Product Information & Multigraph Topology

What is FalkorDB and what makes it unique as a graph database?

FalkorDB is a high-performance, open-source graph database designed for managing complex, interconnected data in real-time or interactive environments. It stands out for its ultra-low latency, linear scalability, and robust multi-tenancy, supporting over 10,000 isolated graphs per deployment. FalkorDB is optimized for advanced AI applications, such as GraphRAG and agent memory, and is trusted by organizations in healthcare, media, and AI development. Learn more.

How does FalkorDB's multigraph topology support scalability and isolation?

FalkorDB's multigraph topology enables each graph to be fully isolated, ensuring that queries target a single graph key. This design eliminates the need for second-label filters and reduces the risk of data leakage. The architecture allows for linear throughput growth as compute resources are added, with minimal coordination overhead across shards. This makes FalkorDB ideal for multi-tenant SaaS applications and large-scale enterprise deployments. Source

Is the multigraph feature available in the open-source version of FalkorDB?

Yes, the multigraph feature is fully available in the open-source version of FalkorDB, with no distinction from the managed service. This ensures all users can benefit from robust multi-tenancy and isolation capabilities. Source

How does FalkorDB handle query isolation and prevent data leakage?

FalkorDB ensures query isolation by targeting a single graph key for each query. This approach removes the need for second-label filters and significantly reduces the risk of data leakage between tenants or graphs. Source

Can I run queries across multiple graphs in FalkorDB?

No, queries in FalkorDB target a single graph. Cross-graph queries are not supported within one query execution, ensuring strong isolation and performance. Source

Is there any overhead when adding more graphs in FalkorDB?

Adding more graphs increases memory usage and snapshot duration, but query latency remains unaffected since each query targets a single graph. This allows for efficient scaling without performance degradation. Source

Are multi-tenant graphs a good mechanism for sharding in FalkorDB?

No, multi-tenancy in FalkorDB manages multiple graphs on a single instance, while sharding refers to splitting key-space across machines for horizontal scaling. Both can be used together for optimal scalability. Source

How does FalkorDB scale read operations?

You can add multiple replicas per master in FalkorDB to scale read operations. Each replica increases read throughput proportionally, supporting high QPS workloads. Source

Is there full isolation between masters and replicas in FalkorDB?

Yes, queries run locally on the target master or replica. Read queries do not affect other nodes; only writes trigger replication to replicas, ensuring strong isolation and consistency. Source

What are the observed performance metrics for FalkorDB's multigraph topology?

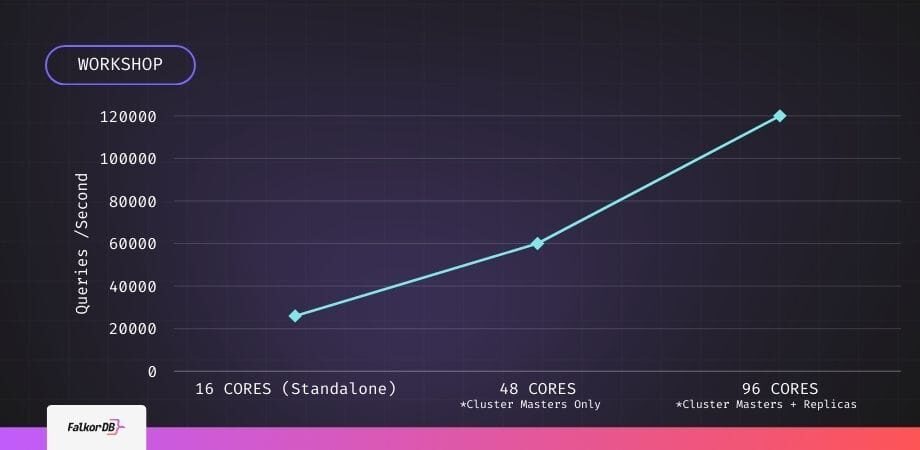
In a real-world test, a single instance (16 cores, 629 isolated graphs) achieved ≈25,000 QPS. A 3-master cluster (48 cores) reached ≈60,000 QPS, and with 3 masters + 3 replicas (96 cores), throughput doubled to ≈120,000 QPS, demonstrating near-linear scaling. Source

How does FalkorDB handle replica lag for read operations?

Replica lag in FalkorDB is negligible for reads, with only a brief propagation delay from master to replica. Write integrity remains master-bound, ensuring data consistency. Source

What is the primary purpose of FalkorDB's multigraph topology?

The primary purpose is to provide scalable, isolated graph workloads for multi-tenant SaaS and enterprise environments, enabling high throughput and strong data isolation for each tenant or application. Source

Who is FalkorDB designed for?

FalkorDB is designed for developers, data scientists, engineers, and security analysts at enterprises and SaaS providers managing complex, interconnected data in real-time or interactive environments. Source

What are some real-world use cases for FalkorDB?

FalkorDB is used for Text2SQL (natural language to SQL on complex schemas), security graphs (CNAPP, CSPM, CIEM), GraphRAG (advanced graph-based retrieval), agentic AI and chatbots, and real-time fraud detection. Source

How does FalkorDB support AI and GenAI applications?

FalkorDB is optimized for AI use cases such as GraphRAG and agent memory, enabling intelligent agents and chatbots with real-time adaptability and accurate, multi-tenant RAG solutions. Source

What technical documentation is available for FalkorDB?

FalkorDB provides comprehensive technical documentation and API references at docs.falkordb.com, including setup guides, advanced configurations, and integration instructions. Source

Does FalkorDB offer an API?

Yes, FalkorDB provides a robust API with detailed references and guides available in the official documentation. This enables seamless integration into developer workflows. Source

What integrations does FalkorDB support?

FalkorDB integrates with frameworks such as Graphiti (by ZEP), g.v() for visualization, Cognee for AI agent memory, LangChain, and LlamaIndex for LLM integration. Source

How does FalkorDB ensure security and compliance?

FalkorDB is SOC 2 Type II compliant, meeting rigorous standards for security, availability, processing integrity, confidentiality, and privacy. This ensures enterprise-grade protection for sensitive data. Source

What support and onboarding resources are available for FalkorDB?

FalkorDB offers comprehensive documentation, community support via Discord and GitHub Discussions, solution architects for tailored advice, and free trial/demo options for onboarding. Source

Performance & Competitive Comparison

How does FalkorDB's performance compare to Neo4j?

FalkorDB offers up to 496x faster latency and 6x better memory efficiency compared to Neo4j. It also supports flexible horizontal scaling and includes multi-tenancy in all plans. Source

How does FalkorDB compare to AWS Neptune?

FalkorDB is open source, supports multi-tenancy, and provides better latency performance and memory efficiency than AWS Neptune, which is proprietary and lacks multi-tenancy support. Source

What are the advantages of FalkorDB over TigerGraph and ArangoDB?

FalkorDB delivers faster latency, more efficient memory usage, and flexible horizontal scaling compared to TigerGraph and ArangoDB, making it ideal for performance-critical and large-scale applications. Source

What pain points does FalkorDB solve for its users?

FalkorDB addresses trust and reliability in LLM-based applications, scalability and data management challenges, alert fatigue in cybersecurity, performance limitations of competitors, and regulatory compliance needs. Source

What business impact can customers expect from using FalkorDB?

Customers can expect improved scalability, enhanced trust and reliability, reduced alert fatigue, faster time-to-market, better user experience, regulatory compliance, and support for advanced AI applications. Source

What customer feedback has FalkorDB received regarding ease of use?

Customers like AdaptX and 2Arrows have praised FalkorDB for its rapid access to insights, ease of running non-traversal queries, and frictionless user experience. AdaptX Case Study, 2Arrows Feedback

Who are some of FalkorDB's customers?

Notable customers include AdaptX (healthcare analytics), XR.Voyage (media/entertainment), and Virtuous AI (ethical AI development). Case Studies

What industries are represented in FalkorDB's case studies?

Industries include healthcare, media and entertainment, and artificial intelligence/ethical AI development. Source

How long does it take to implement FalkorDB and how easy is it to start?

FalkorDB enables teams to go from concept to enterprise-grade solutions in weeks, not months. Users can sign up for FalkorDB Cloud, try a free instance, or run locally with Docker. Comprehensive documentation and community support are available for onboarding. Source

What pricing plans does FalkorDB offer?

FalkorDB offers a FREE plan for MVPs, a STARTUP plan from /1GB/month (includes TLS and automated backups), a PRO plan from 0/8GB/month (includes cluster deployment and high availability), and an ENTERPRISE plan with custom pricing and features like VPC and 24/7 support. Source

What compliance certifications does FalkorDB have?

FalkorDB is SOC 2 Type II compliant, ensuring high standards for security, availability, processing integrity, confidentiality, and privacy. Source

What are the key capabilities and benefits of FalkorDB?

Key capabilities include support for 10,000+ multi-graphs, open-source licensing, linear scalability, ultra-low latency, GraphRAG and agent memory optimization, and flexible deployment (cloud/on-prem). Benefits include trust, reliability, scalability, enhanced user experience, and regulatory compliance. Source

How does FalkorDB help with regulatory compliance?

FalkorDB's GraphRAG-SDK helps organizations stay ahead of financial regulations by mapping regulations to workflows, identifying compliance gaps, and providing actionable recommendations. Source

What customer success stories are available for FalkorDB?

Case studies include AdaptX (healthcare analytics), XR.Voyage (media/entertainment), and Virtuous AI (ethical AI development), each leveraging FalkorDB for high-performance, scalable, and reliable data solutions. Case Studies

Can a Redis-Based Graph Database Scale for Enterprise AI? Multigraph Topology Explained

Multigraph Topology for Scalable, Isolated Graph Workloads

Yes, a Redis-based graph database can scale for enterprise AI when workloads are designed around bounded graph traversals, multiple isolated graphs, and a read/write architecture that uses replicas for read-heavy traffic. FalkorDB clusters distribute graph keys across master shards, while replicas provide failover and read scaling. Capacity still depends on graph shape, memory sizing, query depth, tenant count, and write volume.

What is multigraph topology?

Multigraph topology stores each tenant or workload in its own isolated graph key. In a FalkorDB cluster, those graph keys can be distributed across master shards while each individual graph remains on one shard. This architecture supports tenant isolation, predictable query boundaries, and throughput growth across many independent graph workloads.

Recap

FalkorDB’s team assessed how a multi-tenant graph database handles an access-permission workload and whether throughput scales when moving from a single server to a clustered deployment. The workshop used a real-world pattern—“Does user X have permission to file Y?”—and measured query-per-second (QPS) under three hardware configurations.

What does Redis-based mean for a graph database?

FalkorDB is a graph database built as a Redis module. It runs inside a Redis process and exposes graph operations as Redis commands, so a graph is addressed as a Redis key and queried with Cypher.

Redis compatibility is what that buys you operationally: the RESP protocol, the Redis clients your team already uses in most languages, and familiar tooling for persistence, replication, monitoring, and cluster management. That is an integration and operations benefit. It is not, by itself, evidence of query performance.

It is also not merely a cache or a key-value layer with graph naming on top. FalkorDB stores graph structures in memory and represents adjacency using sparse matrices, so traversals are executed as linear-algebra operations over those matrices rather than as pointer chasing through key lookups.

Because of that, traversal performance tracks the work a query actually does. Graph shape, traversal depth, fan-out at each hop, available memory, index coverage, and query design all matter. A shallow, indexed, well-anchored lookup and an unbounded multi-hop traversal over the same graph behave very differently, on any hardware.

What scales in a FalkorDB cluster?

A FalkorDB cluster scales by distributing graphs, not by splitting an individual graph.

  • Graph keys are distributed across master shards. Different graphs hash to different slots, so they can be spread across multiple masters.
  • A graph is a single Redis key and stays on one shard. All of a graph’s data lives on the master that owns its slot.
  • Multiple masters increase throughput across many graphs. Aggregate capacity grows as you add masters, because concurrent queries against different graphs land on different nodes.
  • Replicas scale read-heavy workloads and provide failover. Each master can have replicas that serve read-only queries and can be promoted if the master is lost.
  • Writes remain primary-bound. A graph’s write capacity is the capacity of its master.
  • A cluster does not split one graph across multiple shards. Horizontal scale comes from having many graphs, not from partitioning a single one.
  • Cross-graph queries are not supported within one query execution. Combining data from several graphs is an application-layer concern.

This shape suits multi-tenant systems well, and it suits a single enormous graph poorly. Setup and scaling steps are covered in the FalkorDB cluster architecture documentation.

Measured enterprise scaling results

The figures below were measured in a FalkorDB workshop that tested whether throughput scales when the same workload moves from one server to a cluster, and then to a cluster with read replicas.

Methodology. The workload modelled an access-permission query of the form “Does user X have permission to access file Y?” — a bounded, anchored traversal executed against many small isolated tenant graphs, 629 of them in the single-instance test. Throughput is reported as mean queries per second (QPS) under sustained load across three hardware configurations.

Test setupTotal coresGraph layout and test conditionsMean QPS (measured)Scaling observation
Single instance (baseline)16629 isolated graphs on one node; single master, no replicas≈ 25 kBaseline
3-master cluster48Graphs distributed by key-space slots across three masters; no replicas≈ 60 kTripling compute raised throughput ~2.4×, close to linear
3 masters + 3 replicas96Masters handle writes; three replicas added as read targets≈ 120 kDoubling compute again doubled read throughput, sustaining the linear trend in this test

Treat these figures as benchmark or workshop results for one workload shape, not as a universal capacity guarantee or an enterprise SLA. They show how throughput responded when this specific access-permission workload was scaled out; they do not establish that any workload will scale the same way.

Measured results on your own system will differ with:

  • Graph size and topology
  • Number of tenants
  • Query complexity
  • Traversal depth and fan-out
  • Read/write ratio
  • Hardware
  • Memory availability
  • Network conditions
  • Client and deployment configuration

Key Observations

  • Throughput grew close to linearly in this test. Each roughly 32-core increment raised measured capacity approximately in proportion to the added compute, which indicates low coordination overhead across shards for this access pattern.

  • Graph isolation at query time. Every query targets a single graph key, removing the need for second-label filters and reducing the risk of cross-tenant data leakage.

  • Replica lag was small for reads under this load. The team observed only a brief propagation delay from master to replica; write integrity remains master-bound. Replication is asynchronous, so lag should still be monitored under heavier write volumes.

How read and write scaling work

FalkorDB uses a single-primary model: each shard has one master that owns its graphs, plus optional replicas.

  • Masters handle writes. Every write to a graph goes to the master that owns that graph’s hash slot.
  • Replicas serve read-only traffic. A replica will reject writes, so read queries can be routed to it safely.
  • Replication is asynchronous. The master acknowledges a write and then streams it to its replicas, so a replica can briefly return a slightly older view of the graph.
  • Replicas can improve read throughput and provide failover capacity. Adding read targets increases the aggregate read capacity behind a master and gives you a node that can be promoted if that master is lost.
  • Monitor replication lag under heavy write load. If lag matters for a given query, send that query to the master rather than a replica.
  • Replicas do not increase write throughput. Write capacity for a graph is bounded by its primary, regardless of how many replicas are attached.
  • High availability needs an explicit configuration. Replication alone is not automatic failover; you need an appropriate cluster or failover setup to promote a replica without manual intervention.

The master–replica setup is documented in FalkorDB replication and read scaling.

What does not scale automatically?

Several things do not improve just by adding hardware. These constraints matter more than headline throughput when you are sizing an enterprise deployment.

  • One graph is not split across multiple shards. A graph is a single Redis key, so it lives entirely on one master. A single very large graph is bounded by the capacity of the shard that holds it.
  • Cross-graph queries cannot be combined into one query execution. A query targets one graph; results from several graphs must be joined in the application layer.
  • Replicas do not increase write throughput. Read scaling and write scaling are separate problems, and only the first is solved by adding replicas.
  • Memory usage increases as graphs and data volume increase. Graph data is held in memory, so capacity planning is primarily memory planning.
  • Snapshot time can increase as data volume grows. That affects persistence windows, backup duration, and recovery time objectives.
  • Deep or high-fan-out traversals require tuning. An unbounded multi-hop traversal can do far more work than a bounded, anchored one on the same graph, and no amount of sharding fixes an unbounded query.
  • Enterprise capacity must be validated against your own workload. Published benchmarks describe the workload that was measured, not the workload you intend to run.

How this applies to enterprise AI and GraphRAG

The multigraph-plus-replica topology maps onto several enterprise AI patterns, because most of them are read-heavy, tenant-scoped, and anchored on a known starting entity.

  • Multi-tenant knowledge graphs. One graph per tenant gives isolation at the key level, so a query cannot accidentally traverse into another tenant’s data.
  • Permission-aware retrieval. The benchmarked access-check pattern has the same shape as filtering retrieval by entitlement before content reaches the model.
  • GraphRAG context retrieval. A bounded traversal from an anchor node assembles a context subgraph, which is a more targeted input than a flat list of similar chunks.
  • Agent memory. Agents can persist entities, relationships, and history as a graph and read it back with structured queries instead of re-embedding everything.
  • Low-latency relationship queries. In-memory adjacency keeps short, indexed traversals cheap enough to sit inside a request path.
  • Read-heavy inference workloads. Retrieval traffic can be directed to replicas where slightly stale reads are acceptable.

Whether relationship traversal or vector similarity is the right primitive for a given retrieval step is a separate design decision — see this graph and vector database comparison.

In practice, scaling AI retrieval depends less on cluster size than on keeping each retrieval bounded:

  • Anchor-node selection. Start from a specific, indexed entity rather than scanning for a starting point.
  • Hop limits. Set an explicit maximum traversal depth in the query.
  • Fan-out limits. Cap how many neighbours are expanded per hop so a hub node cannot blow up the result set.
  • Property indexes. Index the properties used for anchor lookup and filtering.
  • Tenant-aware graph selection. Resolve the tenant to a graph key before the query runs.
  • Read replicas where appropriate. Route retrieval reads to replicas when asynchronous replication is acceptable for that call.
  • p95 and p99 latency monitoring. Track tail latency rather than averages, because tail behaviour is what users and agent loops actually experience.

These practices make retrieval cost predictable. They do not guarantee that any particular latency or throughput target will be met — that has to be measured against your own workload.

Enterprise sizing and load-testing checklist

Use this checklist to gather the inputs needed to size a deployment and to design a load test that reflects real traffic.

  • Number of tenants or graphs, now and at your planning horizon
  • Nodes and edges per graph, including the largest expected graph
  • Expected graph growth rate
  • Concurrent reads at peak
  • Concurrent writes at peak
  • Read/write ratio
  • Average and maximum traversal depth
  • Query fan-out per hop
  • p95 and p99 latency targets
  • Memory requirements, including headroom for growth and snapshots
  • Snapshot and recovery requirements, including recovery time objectives
  • Replication lag tolerance per query class
  • Failover objectives and who or what performs promotion
  • Cross-region or multi-zone requirements
  • Authentication and tenant-isolation requirements

Test with representative, production-shaped data rather than synthetic averages alone. Averaged test data tends to hide the cases that actually cause trouble: hub nodes with very high degree, unusually large tenants, and skewed access patterns where a small number of graphs receive most of the traffic.

Frequently asked questions

Can a Redis-based graph database scale for enterprise AI workloads?

Yes, within a defined architecture. FalkorDB runs as a Redis module and scales horizontally by distributing many isolated graphs across master shards, with replicas absorbing read-heavy traffic. It scales well for bounded, anchored traversals over many tenant graphs. It does not scale by splitting one graph across shards, and capacity always depends on graph shape, memory, query depth, tenant count, and write volume.

How does FalkorDB scale across multiple graph databases?

Each graph is a separate Redis key, so graphs hash to different slots and can be distributed across multiple master shards. Adding masters increases aggregate throughput across a population of graphs, because queries against different graphs execute on different nodes.

Can FalkorDB split one graph across multiple shards?

No. A graph is a single Redis key and lives entirely on one master shard. Horizontal scale comes from running many graphs across many masters, not from partitioning an individual graph.

How does FalkorDB support read scaling?

Each master can have read-only replicas that serve read queries, which raises aggregate read capacity behind that master. Replication is asynchronous, so a replica may return a slightly older view of the graph; queries that need the newest write should be sent to the master.

Do replicas increase FalkorDB write throughput?

No. All writes for a graph go to the master that owns it, so write capacity is bounded by that primary no matter how many replicas are attached. Replicas add read capacity and failover capacity only.

Can I add more replicas to achieve more operations per second?

You can add multiple replicas per master to scale read operations, and in the workshop benchmark adding three replicas roughly doubled measured read throughput. Gains apply to reads only and are not guaranteed to be proportional in every workload — network capacity, replication load on the master, and query mix all affect the result.

What happens if a FalkorDB master fails?

The graphs owned by that master become unavailable until a replica is promoted to take over its slots. Replication on its own is not automatic failover, so high availability requires an appropriate cluster or failover configuration to handle promotion.

Is there full isolation between masters and replicas?

Yes. Queries run locally on the target master or replica. Read queries do not affect other nodes; only writes trigger replication from the master to its replicas.

How does multigraph architecture support SaaS tenant isolation?

Giving each tenant its own graph makes isolation structural rather than a filter condition. A query names one graph key, so it cannot traverse into another tenant’s data, and no second-label filter is needed to keep tenants apart. Tenant graphs can also be sized, backed up, and moved independently.

Are multi-tenant graphs a good mechanism for sharding?

No. Multi-tenancy is about managing multiple graphs, while sharding refers to splitting the key space across machines for horizontal scaling. The two work together — many tenant graphs distributed across shards — but one is not a substitute for the other.

Can I run a query distributed between multiple graphs and return one result set?

No. A query in FalkorDB targets a single graph, and cross-graph queries are not supported within one query execution. Results from multiple graphs must be combined in the application layer.

Is there any overhead when adding more graphs?

Memory usage increases and snapshots take longer as the number of graphs grows. Query latency is largely unaffected, because each query targets a single graph rather than scanning across all of them.

Is the multigraph functionality available in the open-source version of FalkorDB?

Yes. The multigraph feature is fully available in the open-source version, with no distinction from the managed service.

Can FalkorDB run GraphRAG workloads at scale?

It fits GraphRAG well when retrieval is bounded: anchor on an indexed entity, cap hop depth and fan-out, select the tenant graph up front, and route read traffic to replicas where slightly stale reads are acceptable. Whether a specific latency or throughput target is met still has to be verified against your own data and query patterns.

What are the limitations of FalkorDB clustering?

A single graph cannot be split across shards; cross-graph queries cannot be combined into one execution; replicas add read capacity but not write capacity; memory usage and snapshot duration grow with data volume; and deep or high-fan-out traversals need explicit tuning.

How should I benchmark FalkorDB for an enterprise AI workload?

Reproduce your real query shapes against production-shaped data rather than synthetic averages. Model the expected number of tenant graphs, the size of your largest graph, your read/write ratio, and your true traversal depth and fan-out, then measure p95 and p99 latency alongside throughput. Include hub nodes and skewed access patterns, since those drive tail latency.

Build fast and accurate GenAI apps with GraphRAG SDK at scale

FalkorDB offers an accurate, multi-tenant RAG solution based on our low-latency, scalable graph database technology. It’s ideal for highly technical teams that handle complex, interconnected data in real-time, resulting in fewer hallucinations and more accurate responses from LLMs.

Author

  • Roi Lipman

    Roi Lipman serves as CTO at FalkorDB, leading the development of ultra-low-latency graph database platforms for generative AI and retrieval-augmented generation (RAG) workflows. He brings over 20 years of database engineering expertise from roles at Forter, StreamRail, Maglan, AVG and the Israel Intelligence Corps. As creator and lead architect of RedisGraph for the past eight years, he optimized Cypher-based knowledge graph performance for enterprise-scale AI applications.